 LAGEN
Are Vision-Language Agents Latency Aware?
Training agents for a world that keeps moving
1 Northwestern2 UMass Amherst3 Stanford4 UT Austin5 NVIDIA
While a VLA agent calculates an action, the environment continues to move. When the action starts, the state is already different. On an RTX 3090 in real time, the median return of 36 VLA policies is only 6.6% of their return without latency. LAGEN measures the latency of a deployment and trains agents to act correctly with it.
 Models
A small delay makes the same actions fail
Both videos start from the same state and use the same actions. The right video applies each action later, as on a real GPU. Move the slider to change the delay.
Evaluation that stops the environment hides the effect of latency
This failure is not specific to one episode. On Flappy Bird and Demon Attack, we add a delay of only two frames. The return then falls to 1.2–7.1% of the return without delay.
Flappy Bird
Demon Attack
Deadly Corridor
Intercept Grab (Fast)
Focus a chart and use the left and right arrow keys to inspect latency columns. Press Escape to dismiss values. On touch screens, tap a column.
Faster inference does not remove latency. Train with latency.
Faster inference makes the latency smaller, but the latency does not become zero. Thus, we keep the latency and train the agent to act with it.
Reduce latency
Make inference faster. Predict new actions while the agent does the current actions.
Train with latency (ours)
latency profile
Use the deployment latency in simulation. Train agents to act with this latency.
Result: training with latency increases the real-time return for all 36 combinations of task and model.
Show results for all 12 tasks
Demon Attack · OpenVLA
- Before training
- 24.74%
- After training
- 61.50%
Demon Attack · π₀.₅
- Before training
- 4.78%
- After training
- 38.59%
Demon Attack · GR00T
- Before training
- 9.78%
- After training
- 50.74%
Asterix · OpenVLA
- Before training
- 6.45%
- After training
- 62.95%
Asterix · π₀.₅
- Before training
- 2.49%
- After training
- 17.63%
Asterix · GR00T
- Before training
- 3.19%
- After training
- 25.20%
Atlantis · OpenVLA
- Before training
- 46.99%
- After training
- 99.16%
Atlantis · π₀.₅
- Before training
- 11.03%
- After training
- 66.76%
Atlantis · GR00T
- Before training
- 20.59%
- After training
- 71.83%
AirRaid · OpenVLA
- Before training
- 43.94%
- After training
- 117.69%
AirRaid · π₀.₅
- Before training
- 71.32%
- After training
- 166.05%
AirRaid · GR00T
- Before training
- 34.92%
- After training
- 75.49%
Deadly Corridor · OpenVLA
- Before training
- 35.37%
- After training
- 99.65%
Deadly Corridor · π₀.₅
- Before training
- 6.70%
- After training
- 68.95%
Deadly Corridor · GR00T
- Before training
- 16.27%
- After training
- 99.54%
Flappy Bird · OpenVLA
- Before training
- 4.37%
- After training
- 85.12%
Flappy Bird · π₀.₅
- Before training
- 1.37%
- After training
- 84.28%
Flappy Bird · GR00T
- Before training
- 1.54%
- After training
- 96.74%
Ant · OpenVLA
- Before training
- 2.29%
- After training
- 39.02%
Ant · π₀.₅
- Before training
- 1.60%
- After training
- 55.01%
Ant · GR00T
- Before training
- 2.26%
- After training
- 50.48%
Hopper · OpenVLA
- Before training
- 0.32%
- After training
- 127.51%
Hopper · π₀.₅
- Before training
- 0.23%
- After training
- 76.89%
Hopper · GR00T
- Before training
- 0.36%
- After training
- 154.19%
Inverted Pendulum · OpenVLA
- Before training
- 1.98%
- After training
- 58.69%
Inverted Pendulum · π₀.₅
- Before training
- 2.01%
- After training
- 83.04%
Inverted Pendulum · GR00T
- Before training
- 1.55%
- After training
- 100.00%
Walker2D · OpenVLA
- Before training
- 5.21%
- After training
- 191.30%
Walker2D · π₀.₅
- Before training
- 2.37%
- After training
- 104.77%
Walker2D · GR00T
- Before training
- 2.53%
- After training
- 106.42%
Balance · OpenVLA
- Before training
- 18.42%
- After training
- 41.60%
Balance · π₀.₅
- Before training
- 14.26%
- After training
- 22.01%
Balance · GR00T
- Before training
- 16.95%
- After training
- 33.80%
Intercept Grab (Fast) · OpenVLA
- Before training
- 51.50%
- After training
- 71.32%
Intercept Grab (Fast) · π₀.₅
- Before training
- 21.97%
- After training
- 47.73%
Intercept Grab (Fast) · GR00T
- Before training
- 42.71%
- After training
- 75.30%
Hover or tap to inspect values. Focus a chart and use the arrow keys to move between readings. Press Escape to close.
| Games | Embodied Control | ||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Model | Condition | DemonAttack | Asterix | Atlantis | AirRaid | DeadlyCorridor | FlappyBird | Ant | Hopper | InvertedPendulum | Walker2D | Balance(simple) | InterceptGrabFast |
| OpenVLA | Zero/Zero | 2.36k | 5.80k | 39.56k | 2.00k | 2.10k | 439.1 | 5.77k | 2.67k | 1.00k | 2.26k | 275.6 | 36.1 |
| Zero/Real | 584.4 | 374.5 | 18.59k | 878.8 | 742.4 | 19.2 | 132.2 | 8.6 | 19.8 | 117.8 | 50.7 | 18.6 | |
| Target/Real | 1.45k↑ | 3.65k↑ | 39.23k↑ | 2.35k↑ | 2.09k↑ | 373.8↑ | 2.25k↑ | 3.40k↑ | 586.9↑ | 4.33k↑ | 114.6↑ | 25.8↑ | |
| π₀.₅ | Zero/Zero | 2.35k | 5.76k | 39.62k | 1.94k | 2.10k | 408.7 | 5.78k | 3.48k | 1.00k | 3.63k | 328.6 | 36.8 |
| Zero/Real | 112.3 | 143.5 | 4.37k | 1.39k | 140.9 | 5.6 | 92.7 | 8.1 | 20.2 | 86.2 | 46.8 | 8.1 | |
| Target/Real | 907.3↑ | 1.02k↑ | 26.45k↑ | 3.23k↑ | 1.45k↑ | 344.5↑ | 3.18k↑ | 2.68k↑ | 830.4↑ | 3.80k↑ | 72.3↑ | 17.6↑ | |
| GR00T | Zero/Zero | 2.37k | 5.71k | 39.66k | 2.10k | 2.10k | 428.5 | 5.94k | 2.41k | 1.00k | 3.72k | 267.5 | 33.5 |
| Zero/Real | 231.9 | 182.0 | 8.17k | 733.8 | 341.8 | 6.6 | 134.2 | 8.6 | 15.6 | 94.0 | 45.3 | 14.3 | |
| Target/Real | 1.20k↑ | 1.44k↑ | 28.49k↑ | 1.59k↑ | 2.09k↑ | 414.5↑ | 3.00k↑ | 3.72k↑ | 1.00k↑ | 3.96k↑ | 90.4↑ | 25.2↑ | |
Can general-purpose agents act with delay?
We test four agents on 12 tasks without task-specific training. They choose actions from observations while the environment keeps moving, using simulated OpenVLA delays.
Results vary by agent and task. On Asterix, GPT-6.1 Sol scores 5.85k; GPT-6 Luna and Claude Haiku 5.5 score zero.
Games
| Agent | DemonAttack | Asterix | Atlantis | AirRaid | DeadlyCorridor | FlappyBird |
|---|---|---|---|---|---|---|
| GPT-6.1 Sol | 668.5 | 5.85k | 18.34k | 567.5 | 313.2 | 17.3 |
| GPT-6 Luna | 90.3 | 0.0 | 0.0 | 68.8 | 111.3 | 3.5 |
| Claude Opus 5.5 | 235.0 | 560.0 | 1.30k | 451.3 | 378.7 | 5.7 |
| Claude Haiku 5.5 | 82.3 | 0.0 | 100.0 | 0.0 | -44.2 | 5.1 |
Embodied control
| Agent | Ant | Hopper | InvertedPendulum | Walker2D | Balance(simple) | InterceptGrabFast |
|---|---|---|---|---|---|---|
| GPT-6.1 Sol | -14.5 | 193.8 | 39.6 | 322.4 | 46.5 | 1.2 |
| GPT-6 Luna | 145.7 | 72.0 | 0.0 | 15.4 | 42.4 | 0.2 |
| Claude Opus 5.5 | 0.3 | 179.9 | 8.9 | 150.0 | 44.7 | 0.6 |
| Claude Haiku 5.5 | -203.1 | 98.6 | 0.0 | 33.3 | 44.7 | 0.3 |
Simulated delays: these scores are not directly comparable to the hardware-timed VLA results above.
How we evaluate the agents
GPT-6.1 Sol and GPT-6 Luna run through Codex; Claude Opus 5.5 and Haiku 5.5 run through Claude Code. All four use Low reasoning effort and select actions directly from observations.
Delays are sampled from measured OpenVLA latency profiles, rather than the agents’ own inference times. Each task uses its native reward scale.
We do not have a matched zero-delay baseline for each agent. Low scores could reflect task competence, the action interface, or latency. These results alone do not show that latency causes the low scores or that task-specific training is necessary. See paper §4.2 and Table 2.
How do we train with latency? First, we make a model of the deployment latency. Then, we train the agent with this model. See the method.
Simulate the deployment latency
First, we find the latency that the agent will have during deployment. We measure the latency on the target hardware and fit a latency profile to the measurements. Then, we use the profile to make new latency sequences in simulation.
Slow requests occur in groups
Two deployments can have the same mean latency but different sequences of latency. Only the Temporal profile shows that slow requests occur together in time.
Show the latency profiles
Action latency (ms)
Density (ms⁻¹)
Action latency (ms)
Density (ms⁻¹)
Action latency (ms)
Density (ms⁻¹)
Action latency (ms)
Density (ms⁻¹)
Action latency (ms)
Density (ms⁻¹)
44 ≤ latency < 46 ms
Requests out of 24,225 per sequence
- Measured
- 0
- Fixed
- 0
- Normal
- 66
- IID
- 0
- Temporal
- 1
46 ≤ latency < 48 ms
Requests out of 24,225 per sequence
- Measured
- 0
- Fixed
- 0
- Normal
- 176
- IID
- 0
- Temporal
- 0
48 ≤ latency < 50 ms
Requests out of 24,225 per sequence
- Measured
- 0
- Fixed
- 0
- Normal
- 367
- IID
- 0
- Temporal
- 0
50 ≤ latency < 52 ms
Requests out of 24,225 per sequence
- Measured
- 0
- Fixed
- 0
- Normal
- 773
- IID
- 0
- Temporal
- 2
52 ≤ latency < 54 ms
Requests out of 24,225 per sequence
- Measured
- 0
- Fixed
- 0
- Normal
- 1,435
- IID
- 0
- Temporal
- 1
54 ≤ latency < 56 ms
Requests out of 24,225 per sequence
- Measured
- 753
- Fixed
- 0
- Normal
- 2,182
- IID
- 0
- Temporal
- 634
56 ≤ latency < 58 ms
Requests out of 24,225 per sequence
- Measured
- 12,429
- Fixed
- 0
- Normal
- 2,856
- IID
- 613
- Temporal
- 10,491
58 ≤ latency < 60 ms
Requests out of 24,225 per sequence
- Measured
- 6,505
- Fixed
- 0
- Normal
- 3,440
- IID
- 16,202
- Temporal
- 5,615
60 ≤ latency < 62 ms
Requests out of 24,225 per sequence
- Measured
- 1,311
- Fixed
- 24,225
- Normal
- 3,515
- IID
- 4,786
- Temporal
- 1,292
62 ≤ latency < 64 ms
Requests out of 24,225 per sequence
- Measured
- 592
- Fixed
- 0
- Normal
- 3,190
- IID
- 1,234
- Temporal
- 673
64 ≤ latency < 66 ms
Requests out of 24,225 per sequence
- Measured
- 375
- Fixed
- 0
- Normal
- 2,484
- IID
- 512
- Temporal
- 433
66 ≤ latency < 68 ms
Requests out of 24,225 per sequence
- Measured
- 152
- Fixed
- 0
- Normal
- 1,754
- IID
- 335
- Temporal
- 196
68 ≤ latency < 70 ms
Requests out of 24,225 per sequence
- Measured
- 89
- Fixed
- 0
- Normal
- 1,021
- IID
- 147
- Temporal
- 86
70 ≤ latency < 72 ms
Requests out of 24,225 per sequence
- Measured
- 44
- Fixed
- 0
- Normal
- 528
- IID
- 82
- Temporal
- 106
72 ≤ latency < 74 ms
Requests out of 24,225 per sequence
- Measured
- 34
- Fixed
- 0
- Normal
- 254
- IID
- 43
- Temporal
- 302
74 ≤ latency < 76 ms
Requests out of 24,225 per sequence
- Measured
- 208
- Fixed
- 0
- Normal
- 98
- IID
- 15
- Temporal
- 317
76 ≤ latency < 78 ms
Requests out of 24,225 per sequence
- Measured
- 334
- Fixed
- 0
- Normal
- 41
- IID
- 1
- Temporal
- 371
78 ≤ latency < 80 ms
Requests out of 24,225 per sequence
- Measured
- 498
- Fixed
- 0
- Normal
- 8
- IID
- 1
- Temporal
- 530
80 ≤ latency < 82 ms
Requests out of 24,225 per sequence
- Measured
- 502
- Fixed
- 0
- Normal
- 3
- IID
- 2
- Temporal
- 527
82 ≤ latency < 84 ms
Requests out of 24,225 per sequence
- Measured
- 238
- Fixed
- 0
- Normal
- 0
- IID
- 5
- Temporal
- 365
84 ≤ latency < 86 ms
Requests out of 24,225 per sequence
- Measured
- 68
- Fixed
- 0
- Normal
- 0
- IID
- 35
- Temporal
- 405
86 ≤ latency < 88 ms
Requests out of 24,225 per sequence
- Measured
- 23
- Fixed
- 0
- Normal
- 0
- IID
- 10
- Temporal
- 257
88 ≤ latency < 90 ms
Requests out of 24,225 per sequence
- Measured
- 14
- Fixed
- 0
- Normal
- 0
- IID
- 12
- Temporal
- 104
90 ≤ latency < 92 ms
Requests out of 24,225 per sequence
- Measured
- 8
- Fixed
- 0
- Normal
- 0
- IID
- 5
- Temporal
- 52
92 ≤ latency < 94 ms
Requests out of 24,225 per sequence
- Measured
- 9
- Fixed
- 0
- Normal
- 0
- IID
- 35
- Temporal
- 110
94 ≤ latency < 96 ms
Requests out of 24,225 per sequence
- Measured
- 11
- Fixed
- 0
- Normal
- 0
- IID
- 109
- Temporal
- 204
96 ≤ latency < 98 ms
Requests out of 24,225 per sequence
- Measured
- 7
- Fixed
- 0
- Normal
- 0
- IID
- 11
- Temporal
- 381
98 ≤ latency < 100 ms
Requests out of 24,225 per sequence
- Measured
- 7
- Fixed
- 0
- Normal
- 0
- IID
- 4
- Temporal
- 333
Hover or focus to highlight. Click or press Enter to keep a selection; repeat to clear it. Use arrow keys to move between choices. Escape clears the selection.
The latency simulation predicts the return on real hardware
Does the latency simulation predict the return on real hardware? With the Temporal profile, the prediction error decreases from 8.93 to 3.81 percentage points. The baseline is a fixed latency that is equal to the mean.
Show simulated and real returns
OpenVLA
Fixed
Normal
IID
Temporal
GR00T
Fixed
Normal
IID
Temporal
Inverted Pendulum · OpenVLA
Fixed · RTX 3090
- Simulated return
- 46.72%
- Real return
- 43.70%
- Sim − real
- +3.02 pp
Inverted Pendulum · OpenVLA
Fixed · RTX 4090
- Simulated return
- 46.72%
- Real return
- 47.71%
- Sim − real
- -1.00 pp
Flappy Bird · OpenVLA
Fixed · L40S
- Simulated return
- 89.82%
- Real return
- 26.97%
- Sim − real
- +62.85 pp
Inverted Pendulum · OpenVLA
Fixed · L40S
- Simulated return
- 46.72%
- Real return
- 30.59%
- Sim − real
- +16.13 pp
Inverted Pendulum · OpenVLA
Fixed · A100
- Simulated return
- 46.72%
- Real return
- 45.80%
- Sim − real
- +0.92 pp
Flappy Bird · OpenVLA
Fixed · RTX 5090
- Simulated return
- 89.82%
- Real return
- 88.72%
- Sim − real
- +1.09 pp
Intercept Grab (Fast) · OpenVLA
Fixed · A100
- Simulated return
- 73.16%
- Real return
- 71.68%
- Sim − real
- +1.48 pp
Intercept Grab (Fast) · OpenVLA
Fixed · L40S
- Simulated return
- 73.16%
- Real return
- 79.14%
- Sim − real
- -5.98 pp
Intercept Grab (Fast) · OpenVLA
Fixed · RTX 3090
- Simulated return
- 73.16%
- Real return
- 79.62%
- Sim − real
- -6.46 pp
Intercept Grab (Fast) · OpenVLA
Fixed · RTX 4090
- Simulated return
- 73.16%
- Real return
- 77.11%
- Sim − real
- -3.95 pp
Intercept Grab (Fast) · OpenVLA
Fixed · RTX 5090
- Simulated return
- 73.16%
- Real return
- 76.94%
- Sim − real
- -3.78 pp
Inverted Pendulum · OpenVLA
Fixed · RTX 5090
- Simulated return
- 46.72%
- Real return
- 44.07%
- Sim − real
- +2.65 pp
Flappy Bird · OpenVLA
Fixed · RTX 3090
- Simulated return
- 89.82%
- Real return
- 90.79%
- Sim − real
- -0.97 pp
Flappy Bird · OpenVLA
Fixed · RTX 4090
- Simulated return
- 89.82%
- Real return
- 88.99%
- Sim − real
- +0.82 pp
Flappy Bird · OpenVLA
Fixed · A100
- Simulated return
- 89.82%
- Real return
- 89.74%
- Sim − real
- +0.07 pp
Inverted Pendulum · OpenVLA
Normal · RTX 3090
- Simulated return
- 46.72%
- Real return
- 43.70%
- Sim − real
- +3.02 pp
Inverted Pendulum · OpenVLA
Normal · RTX 4090
- Simulated return
- 46.72%
- Real return
- 47.71%
- Sim − real
- -1.00 pp
Flappy Bird · OpenVLA
Normal · L40S
- Simulated return
- 86.53%
- Real return
- 26.97%
- Sim − real
- +59.57 pp
Inverted Pendulum · OpenVLA
Normal · L40S
- Simulated return
- 45.03%
- Real return
- 30.59%
- Sim − real
- +14.44 pp
Inverted Pendulum · OpenVLA
Normal · A100
- Simulated return
- 46.72%
- Real return
- 45.80%
- Sim − real
- +0.92 pp
Flappy Bird · OpenVLA
Normal · RTX 5090
- Simulated return
- 89.82%
- Real return
- 88.72%
- Sim − real
- +1.09 pp
Intercept Grab (Fast) · OpenVLA
Normal · A100
- Simulated return
- 75.99%
- Real return
- 71.68%
- Sim − real
- +4.32 pp
Intercept Grab (Fast) · OpenVLA
Normal · L40S
- Simulated return
- 63.66%
- Real return
- 79.14%
- Sim − real
- -15.48 pp
Intercept Grab (Fast) · OpenVLA
Normal · RTX 3090
- Simulated return
- 75.99%
- Real return
- 79.62%
- Sim − real
- -3.62 pp
Intercept Grab (Fast) · OpenVLA
Normal · RTX 4090
- Simulated return
- 75.99%
- Real return
- 77.11%
- Sim − real
- -1.11 pp
Intercept Grab (Fast) · OpenVLA
Normal · RTX 5090
- Simulated return
- 75.99%
- Real return
- 76.94%
- Sim − real
- -0.95 pp
Inverted Pendulum · OpenVLA
Normal · RTX 5090
- Simulated return
- 46.72%
- Real return
- 44.07%
- Sim − real
- +2.65 pp
Flappy Bird · OpenVLA
Normal · RTX 3090
- Simulated return
- 89.82%
- Real return
- 90.79%
- Sim − real
- -0.97 pp
Flappy Bird · OpenVLA
Normal · RTX 4090
- Simulated return
- 89.82%
- Real return
- 88.99%
- Sim − real
- +0.82 pp
Flappy Bird · OpenVLA
Normal · A100
- Simulated return
- 89.82%
- Real return
- 89.74%
- Sim − real
- +0.07 pp
Inverted Pendulum · OpenVLA
IID · RTX 3090
- Simulated return
- 41.44%
- Real return
- 43.70%
- Sim − real
- -2.25 pp
Inverted Pendulum · OpenVLA
IID · RTX 4090
- Simulated return
- 45.99%
- Real return
- 47.71%
- Sim − real
- -1.72 pp
Flappy Bird · OpenVLA
IID · L40S
- Simulated return
- 48.24%
- Real return
- 26.97%
- Sim − real
- +21.27 pp
Inverted Pendulum · OpenVLA
IID · L40S
- Simulated return
- 20.45%
- Real return
- 30.59%
- Sim − real
- -10.14 pp
Inverted Pendulum · OpenVLA
IID · A100
- Simulated return
- 41.63%
- Real return
- 45.80%
- Sim − real
- -4.17 pp
Flappy Bird · OpenVLA
IID · RTX 5090
- Simulated return
- 89.01%
- Real return
- 88.72%
- Sim − real
- +0.28 pp
Intercept Grab (Fast) · OpenVLA
IID · A100
- Simulated return
- 75.99%
- Real return
- 71.68%
- Sim − real
- +4.32 pp
Intercept Grab (Fast) · OpenVLA
IID · L40S
- Simulated return
- 82.01%
- Real return
- 79.14%
- Sim − real
- +2.86 pp
Intercept Grab (Fast) · OpenVLA
IID · RTX 3090
- Simulated return
- 75.99%
- Real return
- 79.62%
- Sim − real
- -3.62 pp
Intercept Grab (Fast) · OpenVLA
IID · RTX 4090
- Simulated return
- 77.54%
- Real return
- 77.11%
- Sim − real
- +0.43 pp
Intercept Grab (Fast) · OpenVLA
IID · RTX 5090
- Simulated return
- 75.99%
- Real return
- 76.94%
- Sim − real
- -0.95 pp
Inverted Pendulum · OpenVLA
IID · RTX 5090
- Simulated return
- 41.44%
- Real return
- 44.07%
- Sim − real
- -2.62 pp
Flappy Bird · OpenVLA
IID · RTX 3090
- Simulated return
- 87.70%
- Real return
- 90.79%
- Sim − real
- -3.08 pp
Flappy Bird · OpenVLA
IID · RTX 4090
- Simulated return
- 84.21%
- Real return
- 88.99%
- Sim − real
- -4.78 pp
Flappy Bird · OpenVLA
IID · A100
- Simulated return
- 89.09%
- Real return
- 89.74%
- Sim − real
- -0.65 pp
Inverted Pendulum · OpenVLA
Temporal · RTX 3090
- Simulated return
- 45.56%
- Real return
- 43.70%
- Sim − real
- +1.86 pp
Inverted Pendulum · OpenVLA
Temporal · RTX 4090
- Simulated return
- 46.72%
- Real return
- 47.71%
- Sim − real
- -1.00 pp
Flappy Bird · OpenVLA
Temporal · L40S
- Simulated return
- 36.83%
- Real return
- 26.97%
- Sim − real
- +9.86 pp
Inverted Pendulum · OpenVLA
Temporal · L40S
- Simulated return
- 32.03%
- Real return
- 30.59%
- Sim − real
- +1.44 pp
Inverted Pendulum · OpenVLA
Temporal · A100
- Simulated return
- 39.84%
- Real return
- 45.80%
- Sim − real
- -5.95 pp
Flappy Bird · OpenVLA
Temporal · RTX 5090
- Simulated return
- 88.27%
- Real return
- 88.72%
- Sim − real
- -0.45 pp
Intercept Grab (Fast) · OpenVLA
Temporal · A100
- Simulated return
- 75.99%
- Real return
- 71.68%
- Sim − real
- +4.32 pp
Intercept Grab (Fast) · OpenVLA
Temporal · L40S
- Simulated return
- 71.42%
- Real return
- 79.14%
- Sim − real
- -7.72 pp
Intercept Grab (Fast) · OpenVLA
Temporal · RTX 3090
- Simulated return
- 75.99%
- Real return
- 79.62%
- Sim − real
- -3.62 pp
Intercept Grab (Fast) · OpenVLA
Temporal · RTX 4090
- Simulated return
- 81.36%
- Real return
- 77.11%
- Sim − real
- +4.26 pp
Intercept Grab (Fast) · OpenVLA
Temporal · RTX 5090
- Simulated return
- 75.99%
- Real return
- 76.94%
- Sim − real
- -0.95 pp
Inverted Pendulum · OpenVLA
Temporal · RTX 5090
- Simulated return
- 46.05%
- Real return
- 44.07%
- Sim − real
- +1.98 pp
Flappy Bird · OpenVLA
Temporal · RTX 3090
- Simulated return
- 82.86%
- Real return
- 90.79%
- Sim − real
- -7.93 pp
Flappy Bird · OpenVLA
Temporal · RTX 4090
- Simulated return
- 81.81%
- Real return
- 88.99%
- Sim − real
- -7.18 pp
Flappy Bird · OpenVLA
Temporal · A100
- Simulated return
- 89.82%
- Real return
- 89.74%
- Sim − real
- +0.07 pp
Inverted Pendulum · GR00T
Fixed · RTX 5090, RTX 3090, A100, RTX 4090
- Simulated return
- 100.00%
- Real return
- 100.00%
- Sim − real
- 0.00 pp
Flappy Bird · GR00T
Fixed · L40S
- Simulated return
- 95.80%
- Real return
- 24.48%
- Sim − real
- +71.32 pp
Inverted Pendulum · GR00T
Fixed · L40S
- Simulated return
- 100.00%
- Real return
- 62.33%
- Sim − real
- +37.67 pp
Intercept Grab (Fast) · GR00T
Fixed · A100
- Simulated return
- 71.48%
- Real return
- 68.84%
- Sim − real
- +2.64 pp
Intercept Grab (Fast) · GR00T
Fixed · L40S
- Simulated return
- 17.00%
- Real return
- 31.57%
- Sim − real
- -14.57 pp
Intercept Grab (Fast) · GR00T
Fixed · RTX 3090
- Simulated return
- 71.48%
- Real return
- 75.66%
- Sim − real
- -4.19 pp
Intercept Grab (Fast) · GR00T
Fixed · RTX 4090
- Simulated return
- 71.48%
- Real return
- 71.37%
- Sim − real
- +0.11 pp
Intercept Grab (Fast) · GR00T
Fixed · RTX 5090
- Simulated return
- 71.48%
- Real return
- 80.14%
- Sim − real
- -8.66 pp
Flappy Bird · GR00T
Fixed · RTX 5090
- Simulated return
- 95.80%
- Real return
- 88.09%
- Sim − real
- +7.71 pp
Flappy Bird · GR00T
Fixed · A100
- Simulated return
- 95.80%
- Real return
- 91.75%
- Sim − real
- +4.05 pp
Flappy Bird · GR00T
Fixed · RTX 3090
- Simulated return
- 95.80%
- Real return
- 92.50%
- Sim − real
- +3.29 pp
Flappy Bird · GR00T
Fixed · RTX 4090
- Simulated return
- 95.80%
- Real return
- 93.41%
- Sim − real
- +2.39 pp
Inverted Pendulum · GR00T
Normal · RTX 5090, RTX 3090, A100, RTX 4090
- Simulated return
- 100.00%
- Real return
- 100.00%
- Sim − real
- 0.00 pp
Flappy Bird · GR00T
Normal · L40S
- Simulated return
- 12.58%
- Real return
- 24.48%
- Sim − real
- -11.90 pp
Inverted Pendulum · GR00T
Normal · L40S
- Simulated return
- 100.00%
- Real return
- 62.33%
- Sim − real
- +37.67 pp
Intercept Grab (Fast) · GR00T
Normal · A100
- Simulated return
- 69.24%
- Real return
- 68.84%
- Sim − real
- +0.40 pp
Intercept Grab (Fast) · GR00T
Normal · L40S
- Simulated return
- 31.87%
- Real return
- 31.57%
- Sim − real
- +0.30 pp
Intercept Grab (Fast) · GR00T
Normal · RTX 3090
- Simulated return
- 69.24%
- Real return
- 75.66%
- Sim − real
- -6.43 pp
Intercept Grab (Fast) · GR00T
Normal · RTX 4090
- Simulated return
- 69.90%
- Real return
- 71.37%
- Sim − real
- -1.48 pp
Intercept Grab (Fast) · GR00T
Normal · RTX 5090
- Simulated return
- 69.24%
- Real return
- 80.14%
- Sim − real
- -10.90 pp
Flappy Bird · GR00T
Normal · RTX 5090
- Simulated return
- 95.80%
- Real return
- 88.09%
- Sim − real
- +7.71 pp
Flappy Bird · GR00T
Normal · A100
- Simulated return
- 95.80%
- Real return
- 91.75%
- Sim − real
- +4.05 pp
Flappy Bird · GR00T
Normal · RTX 3090
- Simulated return
- 95.80%
- Real return
- 92.50%
- Sim − real
- +3.29 pp
Flappy Bird · GR00T
Normal · RTX 4090
- Simulated return
- 95.80%
- Real return
- 93.41%
- Sim − real
- +2.39 pp
Inverted Pendulum · GR00T
IID · RTX 5090, RTX 3090, A100, RTX 4090
- Simulated return
- 100.00%
- Real return
- 100.00%
- Sim − real
- 0.00 pp
Flappy Bird · GR00T
IID · L40S
- Simulated return
- 5.67%
- Real return
- 24.48%
- Sim − real
- -18.81 pp
Inverted Pendulum · GR00T
IID · L40S
- Simulated return
- 50.04%
- Real return
- 62.33%
- Sim − real
- -12.29 pp
Intercept Grab (Fast) · GR00T
IID · A100
- Simulated return
- 75.03%
- Real return
- 68.84%
- Sim − real
- +6.19 pp
Intercept Grab (Fast) · GR00T
IID · L40S
- Simulated return
- 43.13%
- Real return
- 31.57%
- Sim − real
- +11.56 pp
Intercept Grab (Fast) · GR00T
IID · RTX 3090
- Simulated return
- 75.03%
- Real return
- 75.66%
- Sim − real
- -0.63 pp
Intercept Grab (Fast) · GR00T
IID · RTX 4090
- Simulated return
- 68.93%
- Real return
- 71.37%
- Sim − real
- -2.44 pp
Intercept Grab (Fast) · GR00T
IID · RTX 5090
- Simulated return
- 73.59%
- Real return
- 80.14%
- Sim − real
- -6.55 pp
Flappy Bird · GR00T
IID · RTX 5090
- Simulated return
- 95.04%
- Real return
- 88.09%
- Sim − real
- +6.95 pp
Flappy Bird · GR00T
IID · A100
- Simulated return
- 95.80%
- Real return
- 91.75%
- Sim − real
- +4.05 pp
Flappy Bird · GR00T
IID · RTX 3090
- Simulated return
- 95.80%
- Real return
- 92.50%
- Sim − real
- +3.29 pp
Flappy Bird · GR00T
IID · RTX 4090
- Simulated return
- 94.97%
- Real return
- 93.41%
- Sim − real
- +1.57 pp
Inverted Pendulum · GR00T
Temporal · RTX 5090, RTX 3090, A100, RTX 4090
- Simulated return
- 100.00%
- Real return
- 100.00%
- Sim − real
- 0.00 pp
Flappy Bird · GR00T
Temporal · L40S
- Simulated return
- 35.60%
- Real return
- 24.48%
- Sim − real
- +11.12 pp
Inverted Pendulum · GR00T
Temporal · L40S
- Simulated return
- 75.99%
- Real return
- 62.33%
- Sim − real
- +13.66 pp
Intercept Grab (Fast) · GR00T
Temporal · A100
- Simulated return
- 71.29%
- Real return
- 68.84%
- Sim − real
- +2.46 pp
Intercept Grab (Fast) · GR00T
Temporal · L40S
- Simulated return
- 25.86%
- Real return
- 31.57%
- Sim − real
- -5.70 pp
Intercept Grab (Fast) · GR00T
Temporal · RTX 3090
- Simulated return
- 71.29%
- Real return
- 75.66%
- Sim − real
- -4.37 pp
Intercept Grab (Fast) · GR00T
Temporal · RTX 4090
- Simulated return
- 70.36%
- Real return
- 71.37%
- Sim − real
- -1.02 pp
Intercept Grab (Fast) · GR00T
Temporal · RTX 5090
- Simulated return
- 74.89%
- Real return
- 80.14%
- Sim − real
- -5.26 pp
Flappy Bird · GR00T
Temporal · RTX 5090
- Simulated return
- 90.62%
- Real return
- 88.09%
- Sim − real
- +2.54 pp
Flappy Bird · GR00T
Temporal · A100
- Simulated return
- 95.80%
- Real return
- 91.75%
- Sim − real
- +4.05 pp
Flappy Bird · GR00T
Temporal · RTX 3090
- Simulated return
- 95.80%
- Real return
- 92.50%
- Sim − real
- +3.29 pp
Flappy Bird · GR00T
Temporal · RTX 4090
- Simulated return
- 95.80%
- Real return
- 93.41%
- Sim − real
- +2.39 pp
Hover or tap to inspect values. Focus a chart and use the arrow keys to move between readings. Press Escape to close.
How we test the latency simulation
We evaluate OpenVLA and GR00T on three tasks: Flappy Bird, Inverted Pendulum, and Intercept Grab (Fast). We use five GPU types: RTX 3090, RTX 4090, RTX 5090, L40S, and A100.
For each combination, we use 25 runs to fit the latency model and 25 different runs to evaluate it. Each run has two episodes. The latency simulation includes both action delay and inference capacity.
Normalized return error for all combinations, in percentage points: Fixed 8.93, Normal 6.55, IID 4.58, Temporal 3.81. Refer to paper §3.4.
Train agents with the deployment latency
Then, we train the agent with the profile. First, an RL teacher learns to act with the simulated latency. Then, the VLA learns from the actions of the teacher.
-
1Measure the deployment
Measure the latency for the target GPU, model, and task. Fit a profile that also shows groups of slow requests.
-
2Train a teacher with simulated latency
In simulation, each action starts after a latency from the profile. An RL teacher learns to act with this latency.
-
3Teach the VLA
Fine-tune the VLA on the actions of the teacher. DAgger is optional.
-
4Act with the same latency
The VLA receives the task, the latency as text, and optional recent frames.
Full pipeline figure from the paper
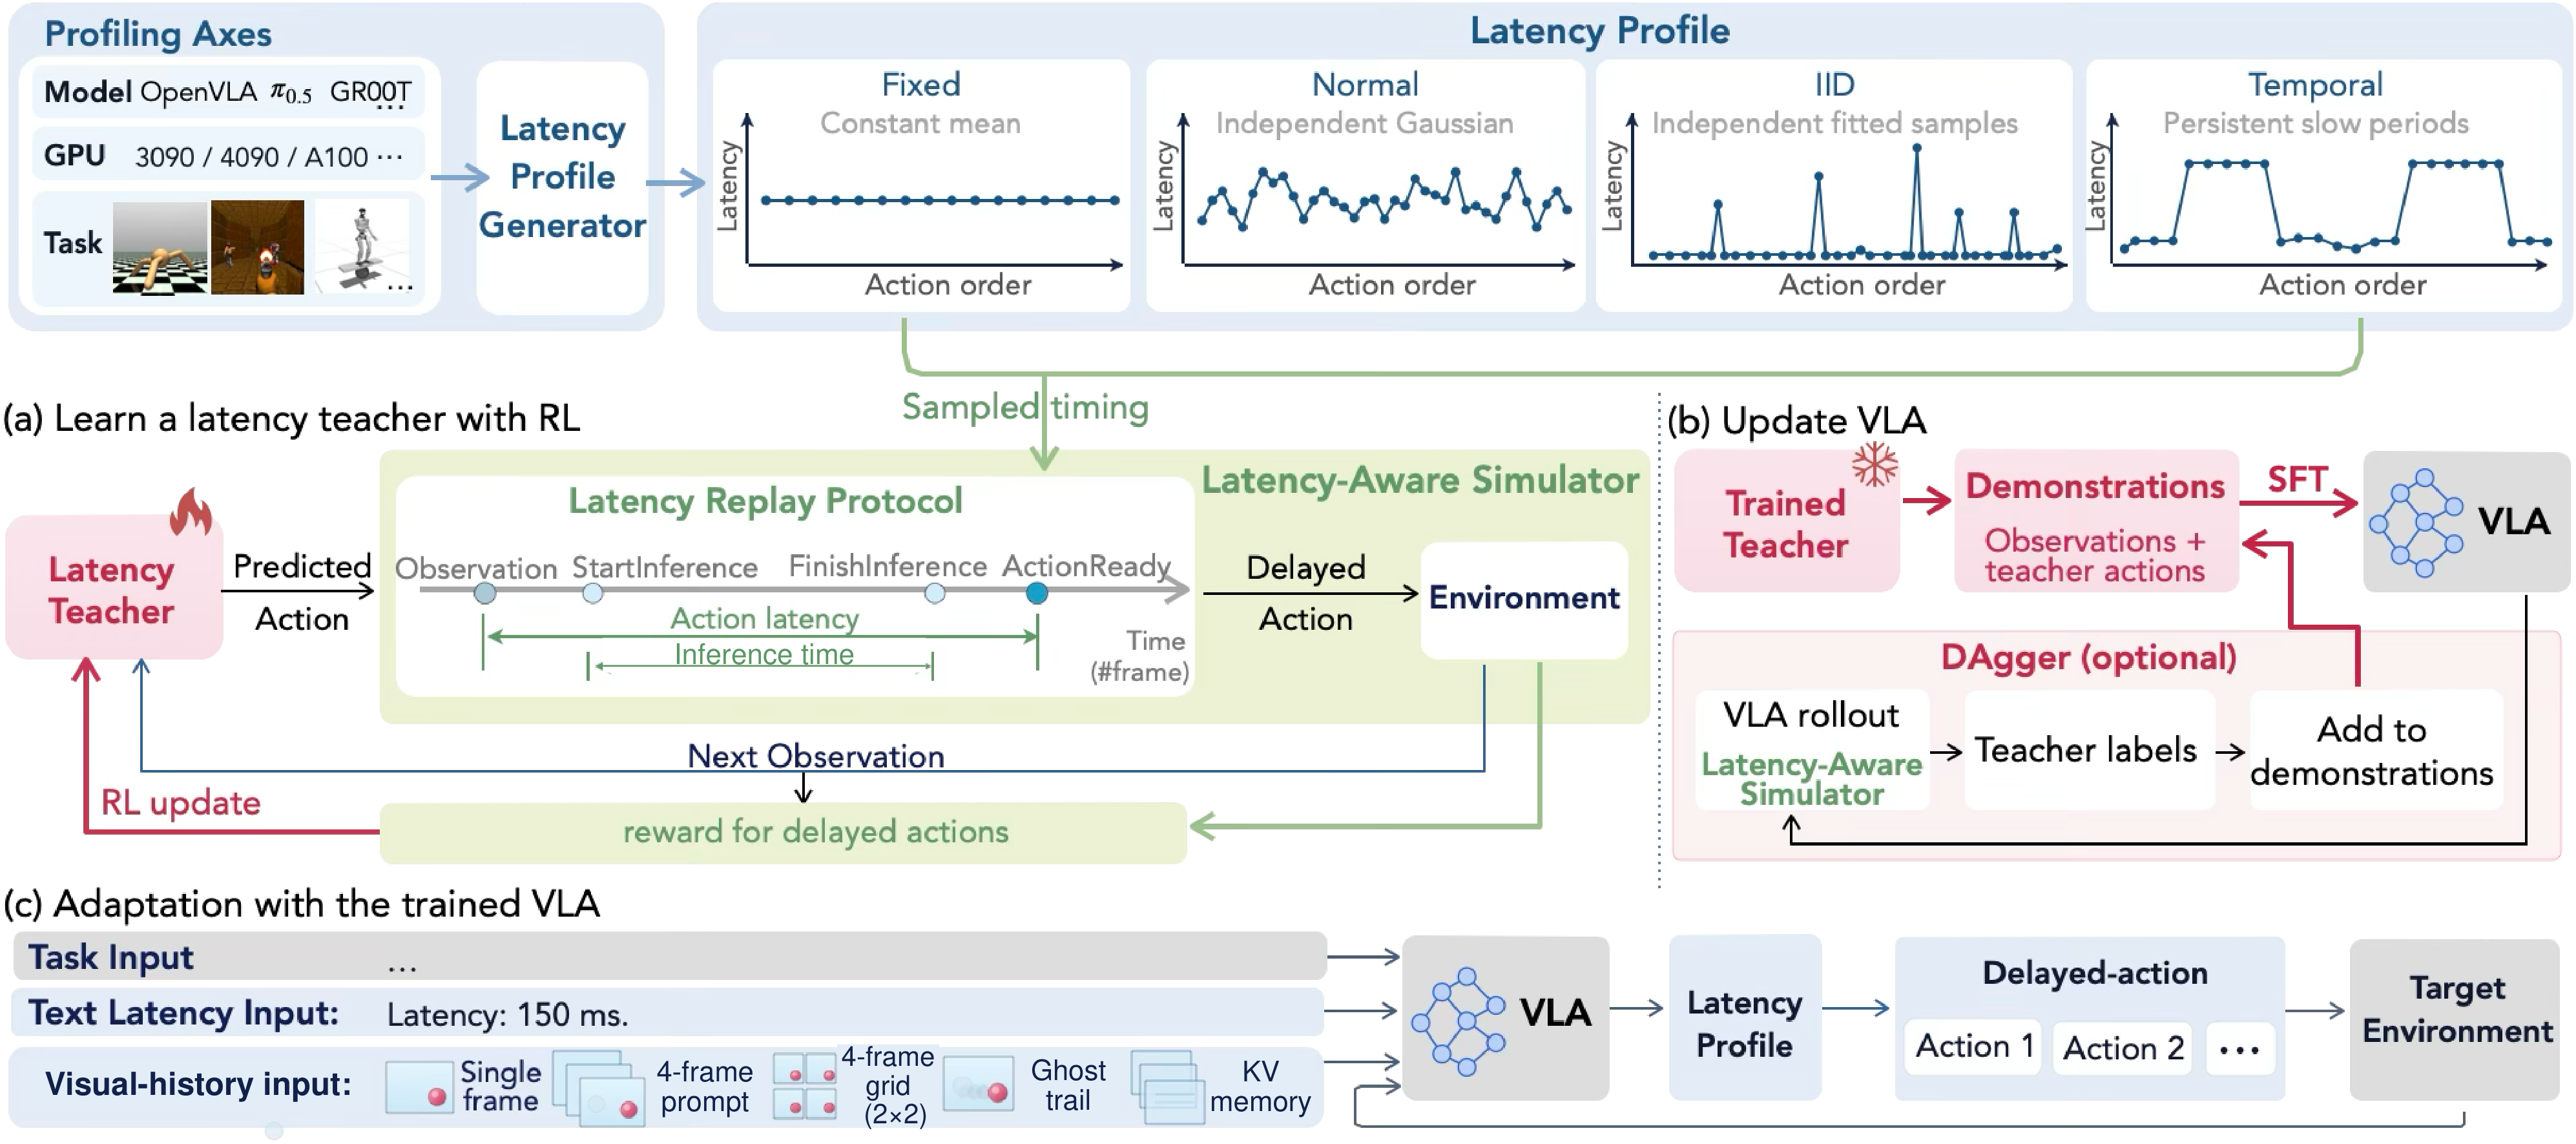
Select the figure to open it at full size. ActionReady shows the time when a predicted action is available. The curves show example latency profiles.
Three questions about latency training
What must we train with? How well does the training transfer? What information does the agent need?
1. Training with the full profile gives a higher return
Is the mean latency sufficient for training? No. Training with the full profile gives a higher return on three of four tasks. On Flappy Bird, the two returns are almost equal.
| Training | Flappy Bird | Deadly Corridor | Ant | Intercept Grab (Fast) |
|---|---|---|---|---|
| Fixed mean | 384.82 | 1620.80 | 1453.84 | 3.54 |
| Full profile | 373.78 | 2091.23 | 1853.33 | 18.20 |
| Profile gain | -2.9% | +29.0% | +27.5% | +413.4% |
2. Transfer from high to low latency is better than from low to high latency
Does a policy work at a latency that is different from its training latency? Transfer from high to low latency is better than transfer from low to high latency. On Flappy Bird, a policy works well only near its training latency.
Return relative to a policy trained at the evaluation latency
Flappy Bird
| 4 | 1.1% | 1.3% | 1.1% | 2.7% | 100.0% |
|---|---|---|---|---|---|
| 3 | 1.5% | 1.4% | 1.3% | 100.0% | 7.0% |
| 2 | 1.5% | 2.2% | 100.0% | 3.7% | 1.8% |
| 1 | 4.1% | 100.0% | 1.6% | 1.6% | 1.4% |
| 0 | 100.0% | 19.7% | 1.8% | 1.5% | 1.4% |
| 0 | 1 | 2 | 3 | 4 |
Flappy Bird
- Train delay
- 0 frames
- Eval delay
- 0 frames
- Relative performance
- 100.0%
Flappy Bird
- Train delay
- 1 frame
- Eval delay
- 0 frames
- Relative performance
- 19.7%
Flappy Bird
- Train delay
- 2 frames
- Eval delay
- 0 frames
- Relative performance
- 1.8%
Flappy Bird
- Train delay
- 3 frames
- Eval delay
- 0 frames
- Relative performance
- 1.5%
Flappy Bird
- Train delay
- 4 frames
- Eval delay
- 0 frames
- Relative performance
- 1.4%
Flappy Bird
- Train delay
- 0 frames
- Eval delay
- 1 frame
- Relative performance
- 4.1%
Flappy Bird
- Train delay
- 1 frame
- Eval delay
- 1 frame
- Relative performance
- 100.0%
Flappy Bird
- Train delay
- 2 frames
- Eval delay
- 1 frame
- Relative performance
- 1.6%
Flappy Bird
- Train delay
- 3 frames
- Eval delay
- 1 frame
- Relative performance
- 1.6%
Flappy Bird
- Train delay
- 4 frames
- Eval delay
- 1 frame
- Relative performance
- 1.4%
Flappy Bird
- Train delay
- 0 frames
- Eval delay
- 2 frames
- Relative performance
- 1.5%
Flappy Bird
- Train delay
- 1 frame
- Eval delay
- 2 frames
- Relative performance
- 2.2%
Flappy Bird
- Train delay
- 2 frames
- Eval delay
- 2 frames
- Relative performance
- 100.0%
Flappy Bird
- Train delay
- 3 frames
- Eval delay
- 2 frames
- Relative performance
- 3.7%
Flappy Bird
- Train delay
- 4 frames
- Eval delay
- 2 frames
- Relative performance
- 1.8%
Flappy Bird
- Train delay
- 0 frames
- Eval delay
- 3 frames
- Relative performance
- 1.5%
Flappy Bird
- Train delay
- 1 frame
- Eval delay
- 3 frames
- Relative performance
- 1.4%
Flappy Bird
- Train delay
- 2 frames
- Eval delay
- 3 frames
- Relative performance
- 1.3%
Flappy Bird
- Train delay
- 3 frames
- Eval delay
- 3 frames
- Relative performance
- 100.0%
Flappy Bird
- Train delay
- 4 frames
- Eval delay
- 3 frames
- Relative performance
- 7.0%
Flappy Bird
- Train delay
- 0 frames
- Eval delay
- 4 frames
- Relative performance
- 1.1%
Flappy Bird
- Train delay
- 1 frame
- Eval delay
- 4 frames
- Relative performance
- 1.3%
Flappy Bird
- Train delay
- 2 frames
- Eval delay
- 4 frames
- Relative performance
- 1.1%
Flappy Bird
- Train delay
- 3 frames
- Eval delay
- 4 frames
- Relative performance
- 2.7%
Flappy Bird
- Train delay
- 4 frames
- Eval delay
- 4 frames
- Relative performance
- 100.0%
Demon Attack
| 32 | 4.8% | 8.1% | 37.8% | 87.5% | 100.0% |
|---|---|---|---|---|---|
| 24 | 3.3% | 6.0% | 24.3% | 100.0% | 65.2% |
| 16 | 4.6% | 27.4% | 100.0% | 66.5% | 51.8% |
| 8 | 4.3% | 100.0% | 84.9% | 64.6% | 32.6% |
| 0 | 100.0% | 64.0% | 36.5% | 24.6% | 23.0% |
| 0 | 8 | 16 | 24 | 32 |
Demon Attack
- Train delay
- 0 frames
- Eval delay
- 0 frames
- Relative performance
- 100.0%
Demon Attack
- Train delay
- 8 frames
- Eval delay
- 0 frames
- Relative performance
- 64.0%
Demon Attack
- Train delay
- 16 frames
- Eval delay
- 0 frames
- Relative performance
- 36.5%
Demon Attack
- Train delay
- 24 frames
- Eval delay
- 0 frames
- Relative performance
- 24.6%
Demon Attack
- Train delay
- 32 frames
- Eval delay
- 0 frames
- Relative performance
- 23.0%
Demon Attack
- Train delay
- 0 frames
- Eval delay
- 8 frames
- Relative performance
- 4.3%
Demon Attack
- Train delay
- 8 frames
- Eval delay
- 8 frames
- Relative performance
- 100.0%
Demon Attack
- Train delay
- 16 frames
- Eval delay
- 8 frames
- Relative performance
- 84.9%
Demon Attack
- Train delay
- 24 frames
- Eval delay
- 8 frames
- Relative performance
- 64.6%
Demon Attack
- Train delay
- 32 frames
- Eval delay
- 8 frames
- Relative performance
- 32.6%
Demon Attack
- Train delay
- 0 frames
- Eval delay
- 16 frames
- Relative performance
- 4.6%
Demon Attack
- Train delay
- 8 frames
- Eval delay
- 16 frames
- Relative performance
- 27.4%
Demon Attack
- Train delay
- 16 frames
- Eval delay
- 16 frames
- Relative performance
- 100.0%
Demon Attack
- Train delay
- 24 frames
- Eval delay
- 16 frames
- Relative performance
- 66.5%
Demon Attack
- Train delay
- 32 frames
- Eval delay
- 16 frames
- Relative performance
- 51.8%
Demon Attack
- Train delay
- 0 frames
- Eval delay
- 24 frames
- Relative performance
- 3.3%
Demon Attack
- Train delay
- 8 frames
- Eval delay
- 24 frames
- Relative performance
- 6.0%
Demon Attack
- Train delay
- 16 frames
- Eval delay
- 24 frames
- Relative performance
- 24.3%
Demon Attack
- Train delay
- 24 frames
- Eval delay
- 24 frames
- Relative performance
- 100.0%
Demon Attack
- Train delay
- 32 frames
- Eval delay
- 24 frames
- Relative performance
- 65.2%
Demon Attack
- Train delay
- 0 frames
- Eval delay
- 32 frames
- Relative performance
- 4.8%
Demon Attack
- Train delay
- 8 frames
- Eval delay
- 32 frames
- Relative performance
- 8.1%
Demon Attack
- Train delay
- 16 frames
- Eval delay
- 32 frames
- Relative performance
- 37.8%
Demon Attack
- Train delay
- 24 frames
- Eval delay
- 32 frames
- Relative performance
- 87.5%
Demon Attack
- Train delay
- 32 frames
- Eval delay
- 32 frames
- Relative performance
- 100.0%
VizDoom Deadly Corridor
| 32 | 36.2% | -0.2% | 65.4% | 52.9% | 100.0% |
|---|---|---|---|---|---|
| 24 | 90.3% | 76.0% | 323.2% | 100.0% | 278.2% |
| 16 | 65.2% | 44.1% | 100.0% | 121.7% | 122.9% |
| 8 | 45.3% | 100.0% | 74.2% | 79.8% | 68.4% |
| 0 | 100.0% | 26.8% | 50.0% | 50.1% | 25.9% |
| 0 | 8 | 16 | 24 | 32 |
VizDoom Deadly Corridor
- Train delay
- 0 frames
- Eval delay
- 0 frames
- Relative performance
- 100.0%
VizDoom Deadly Corridor
- Train delay
- 8 frames
- Eval delay
- 0 frames
- Relative performance
- 26.8%
VizDoom Deadly Corridor
- Train delay
- 16 frames
- Eval delay
- 0 frames
- Relative performance
- 50.0%
VizDoom Deadly Corridor
- Train delay
- 24 frames
- Eval delay
- 0 frames
- Relative performance
- 50.1%
VizDoom Deadly Corridor
- Train delay
- 32 frames
- Eval delay
- 0 frames
- Relative performance
- 25.9%
VizDoom Deadly Corridor
- Train delay
- 0 frames
- Eval delay
- 8 frames
- Relative performance
- 45.3%
VizDoom Deadly Corridor
- Train delay
- 8 frames
- Eval delay
- 8 frames
- Relative performance
- 100.0%
VizDoom Deadly Corridor
- Train delay
- 16 frames
- Eval delay
- 8 frames
- Relative performance
- 74.2%
VizDoom Deadly Corridor
- Train delay
- 24 frames
- Eval delay
- 8 frames
- Relative performance
- 79.8%
VizDoom Deadly Corridor
- Train delay
- 32 frames
- Eval delay
- 8 frames
- Relative performance
- 68.4%
VizDoom Deadly Corridor
- Train delay
- 0 frames
- Eval delay
- 16 frames
- Relative performance
- 65.2%
VizDoom Deadly Corridor
- Train delay
- 8 frames
- Eval delay
- 16 frames
- Relative performance
- 44.1%
VizDoom Deadly Corridor
- Train delay
- 16 frames
- Eval delay
- 16 frames
- Relative performance
- 100.0%
VizDoom Deadly Corridor
- Train delay
- 24 frames
- Eval delay
- 16 frames
- Relative performance
- 121.7%
VizDoom Deadly Corridor
- Train delay
- 32 frames
- Eval delay
- 16 frames
- Relative performance
- 122.9%
VizDoom Deadly Corridor
- Train delay
- 0 frames
- Eval delay
- 24 frames
- Relative performance
- 90.3%
VizDoom Deadly Corridor
- Train delay
- 8 frames
- Eval delay
- 24 frames
- Relative performance
- 76.0%
VizDoom Deadly Corridor
- Train delay
- 16 frames
- Eval delay
- 24 frames
- Relative performance
- 323.2%
VizDoom Deadly Corridor
- Train delay
- 24 frames
- Eval delay
- 24 frames
- Relative performance
- 100.0%
VizDoom Deadly Corridor
- Train delay
- 32 frames
- Eval delay
- 24 frames
- Relative performance
- 278.2%
VizDoom Deadly Corridor
- Train delay
- 0 frames
- Eval delay
- 32 frames
- Relative performance
- 36.2%
VizDoom Deadly Corridor
- Train delay
- 8 frames
- Eval delay
- 32 frames
- Relative performance
- -0.2%
VizDoom Deadly Corridor
- Train delay
- 16 frames
- Eval delay
- 32 frames
- Relative performance
- 65.4%
VizDoom Deadly Corridor
- Train delay
- 24 frames
- Eval delay
- 32 frames
- Relative performance
- 52.9%
VizDoom Deadly Corridor
- Train delay
- 32 frames
- Eval delay
- 32 frames
- Relative performance
- 100.0%
Intercept Grab (Fast)
| 4 | 13.2% | 19.3% | 33.3% | 80.7% | 100.0% |
|---|---|---|---|---|---|
| 3 | 33.8% | 50.8% | 84.6% | 100.0% | 89.2% |
| 2 | 66.9% | 91.9% | 100.0% | 91.9% | 67.4% |
| 1 | 60.1% | 100.0% | 100.0% | 80.9% | 64.9% |
| 0 | 100.0% | 96.4% | 96.4% | 77.9% | 62.6% |
| 0 | 1 | 2 | 3 | 4 |
Intercept Grab (Fast)
- Train delay
- 0 frames
- Eval delay
- 0 frames
- Relative performance
- 100.0%
Intercept Grab (Fast)
- Train delay
- 1 frame
- Eval delay
- 0 frames
- Relative performance
- 96.4%
Intercept Grab (Fast)
- Train delay
- 2 frames
- Eval delay
- 0 frames
- Relative performance
- 96.4%
Intercept Grab (Fast)
- Train delay
- 3 frames
- Eval delay
- 0 frames
- Relative performance
- 77.9%
Intercept Grab (Fast)
- Train delay
- 4 frames
- Eval delay
- 0 frames
- Relative performance
- 62.6%
Intercept Grab (Fast)
- Train delay
- 0 frames
- Eval delay
- 1 frame
- Relative performance
- 60.1%
Intercept Grab (Fast)
- Train delay
- 1 frame
- Eval delay
- 1 frame
- Relative performance
- 100.0%
Intercept Grab (Fast)
- Train delay
- 2 frames
- Eval delay
- 1 frame
- Relative performance
- 100.0%
Intercept Grab (Fast)
- Train delay
- 3 frames
- Eval delay
- 1 frame
- Relative performance
- 80.9%
Intercept Grab (Fast)
- Train delay
- 4 frames
- Eval delay
- 1 frame
- Relative performance
- 64.9%
Intercept Grab (Fast)
- Train delay
- 0 frames
- Eval delay
- 2 frames
- Relative performance
- 66.9%
Intercept Grab (Fast)
- Train delay
- 1 frame
- Eval delay
- 2 frames
- Relative performance
- 91.9%
Intercept Grab (Fast)
- Train delay
- 2 frames
- Eval delay
- 2 frames
- Relative performance
- 100.0%
Intercept Grab (Fast)
- Train delay
- 3 frames
- Eval delay
- 2 frames
- Relative performance
- 91.9%
Intercept Grab (Fast)
- Train delay
- 4 frames
- Eval delay
- 2 frames
- Relative performance
- 67.4%
Intercept Grab (Fast)
- Train delay
- 0 frames
- Eval delay
- 3 frames
- Relative performance
- 33.8%
Intercept Grab (Fast)
- Train delay
- 1 frame
- Eval delay
- 3 frames
- Relative performance
- 50.8%
Intercept Grab (Fast)
- Train delay
- 2 frames
- Eval delay
- 3 frames
- Relative performance
- 84.6%
Intercept Grab (Fast)
- Train delay
- 3 frames
- Eval delay
- 3 frames
- Relative performance
- 100.0%
Intercept Grab (Fast)
- Train delay
- 4 frames
- Eval delay
- 3 frames
- Relative performance
- 89.2%
Intercept Grab (Fast)
- Train delay
- 0 frames
- Eval delay
- 4 frames
- Relative performance
- 13.2%
Intercept Grab (Fast)
- Train delay
- 1 frame
- Eval delay
- 4 frames
- Relative performance
- 19.3%
Intercept Grab (Fast)
- Train delay
- 2 frames
- Eval delay
- 4 frames
- Relative performance
- 33.3%
Intercept Grab (Fast)
- Train delay
- 3 frames
- Eval delay
- 4 frames
- Relative performance
- 80.7%
Intercept Grab (Fast)
- Train delay
- 4 frames
- Eval delay
- 4 frames
- Relative performance
- 100.0%
Hover or tap to inspect values. Focus a chart and use the arrow keys to move between readings. Press Escape to close.
3. Latency training can help on other tasks
Does the training help on other tasks? We train a policy on Demon Attack with mixed latencies. On Atlantis and AirRaid, this policy gets a higher return than a policy trained without latency. On Asterix, the result is mixed.
Demon Attack
Asterix
Atlantis
AirRaid
Demon Attack · 0 frames
Mean return · 20 episodes
- Zero-latency train
- 6113
- Mixed-latency train
- 5812
Demon Attack · 2 frames
Mean return · 20 episodes
- Zero-latency train
- 294
- Mixed-latency train
- 5542
Demon Attack · 4 frames
Mean return · 20 episodes
- Zero-latency train
- 96
- Mixed-latency train
- 3510
Asterix · 0 frames
Mean return · 20 episodes
- Zero-latency train
- 192
- Mixed-latency train
- 230
Asterix · 2 frames
Mean return · 20 episodes
- Zero-latency train
- 202
- Mixed-latency train
- 262
Asterix · 4 frames
Mean return · 20 episodes
- Zero-latency train
- 212
- Mixed-latency train
- 178
Atlantis · 0 frames
Mean return · 20 episodes
- Zero-latency train
- 2000
- Mixed-latency train
- 2000
Atlantis · 2 frames
Mean return · 20 episodes
- Zero-latency train
- 2000
- Mixed-latency train
- 3900
Atlantis · 4 frames
Mean return · 20 episodes
- Zero-latency train
- 2000
- Mixed-latency train
- 5010
AirRaid · 0 frames
Mean return · 20 episodes
- Zero-latency train
- 20
- Mixed-latency train
- 351
AirRaid · 2 frames
Mean return · 20 episodes
- Zero-latency train
- 15
- Mixed-latency train
- 346
AirRaid · 4 frames
Mean return · 20 episodes
- Zero-latency train
- 15
- Mixed-latency train
- 178
Hover or tap to inspect values. Focus a chart and use the arrow keys to move between readings. Press Escape to close.
4. The latency value in the prompt increases the return
At different latencies, the same frame can need different actions. When the prompt gives the latency value, the Flappy Bird return increases from less than 20 to 268–434.
| Task | Delay in prompt | 0 frames | 1 frame | 2 frames | 3 frames | 4 frames |
|---|---|---|---|---|---|---|
| Flappy Bird | Yes | 433.8 | 434.0 | 341.3 | 290.3 | 267.6 |
| Flappy Bird | No | 18.8 | 14.3 | 9.4 | 6.5 | 4.5 |
| Demon Attack | Yes | 7409.0 | 6558.0 | 5551.2 | 4038.0 | 3630.0 |
| Demon Attack | No | 3814.8 | 4392.5 | 4478.8 | 4091.2 | 1995.2 |
| Intercept Grab | Yes | 30.0% | 40.0% | 45.0% | 50.0% | 40.0% |
| Intercept Grab | No | 20.0% | 15.0% | 40.0% | 40.0% | 5.0% |
In each column, the prompt gives the delay of that column.
5. Recent frames in the model input can increase performance
Recent frames show how the scene moved during the latency. The best format for these frames is different for each task.
Return (% of single-frame baseline)
Flappy Bird
Delay: 3 frames
Demon Attack
Delay: 6 frames
Deadly Corridor
Delay: 6 frames
Flappy Bird · Single frame
- Return
- 100.00%
- 95% interval
- 92.97–107.03%
- Episodes
- 100
- Delay
- 3 raw frames
Flappy Bird · Ghost trail
- Return
- 115.73%
- 95% interval
- 112.02–119.43%
- Episodes
- 100
- Delay
- 3 raw frames
Flappy Bird · KV memory
- Return
- 103.62%
- 95% interval
- 96.81–110.44%
- Episodes
- 100
- Delay
- 3 raw frames
Flappy Bird · 4-frame prompt
- Return
- 95.44%
- 95% interval
- 87.80–103.08%
- Episodes
- 100
- Delay
- 3 raw frames
Flappy Bird · 4-frame grid (2×2)
- Return
- 93.02%
- 95% interval
- 85.01–101.03%
- Episodes
- 100
- Delay
- 3 raw frames
Flappy Bird · WanOFT
- Return
- 115.30%
- 95% interval
- 106.32–124.28%
- Episodes
- 20
- Delay
- 3 raw frames
Demon Attack · Single frame
- Return
- 100.00%
- 95% interval
- 97.77–102.23%
- Episodes
- 100
- Delay
- 6 raw frames
Demon Attack · Ghost trail
- Return
- 100.30%
- 95% interval
- 94.79–105.81%
- Episodes
- 100
- Delay
- 6 raw frames
Demon Attack · KV memory
- Return
- 114.31%
- 95% interval
- 112.38–116.25%
- Episodes
- 100
- Delay
- 6 raw frames
Demon Attack · 4-frame prompt
- Return
- 114.15%
- 95% interval
- 112.08–116.23%
- Episodes
- 100
- Delay
- 6 raw frames
Demon Attack · 4-frame grid (2×2)
- Return
- 101.97%
- 95% interval
- 98.22–105.71%
- Episodes
- 100
- Delay
- 6 raw frames
Demon Attack · WanOFT
- Return
- 81.26%
- 95% interval
- 68.66–93.86%
- Episodes
- 20
- Delay
- 6 raw frames
Deadly Corridor · Single frame
- Return
- 100.00%
- 95% interval
- 77.89–122.11%
- Episodes
- 100
- Delay
- 6 raw frames
Deadly Corridor · Ghost trail
The ghost trail is not suitable for first-person games such as Deadly Corridor. Thus, we did not evaluate this condition.
Deadly Corridor · KV memory
- Return
- 98.80%
- 95% interval
- 84.50–113.09%
- Episodes
- 100
- Delay
- 6 raw frames
Deadly Corridor · 4-frame prompt
- Return
- 97.89%
- 95% interval
- 83.27–112.50%
- Episodes
- 100
- Delay
- 6 raw frames
Deadly Corridor · 4-frame grid (2×2)
- Return
- 116.84%
- 95% interval
- 92.39–141.28%
- Episodes
- 100
- Delay
- 6 raw frames
Deadly Corridor · WanOFT
- Return
- 102.99%
- 95% interval
- 70.99–134.99%
- Episodes
- 20
- Delay
- 6 raw frames
Hover or focus to highlight. Click or press Enter to keep a selection; repeat to clear it. Use arrow keys to move between choices. Escape clears the selection.
Citation
@misc{chafekar2026lagen,
  title={LAGEN: Are Vision-Language Agents Latency Aware?},
  author={Talha Chafekar and Zihan Wang and Zeju Li and Xinyuan Li and Qineng Wang and Jiajun Wu and Yuke Zhu and Yi Dong and Zhiding Yu and Ruohan Zhang and Manling Li},
  year={2026}
}